The moment a nonexistent paper appears
Ask an AI to recommend relevant papers and you get a list with authors, years and titles. The format is perfect. Then you look them up and they are not there. The authors exist, the journal exists, only that paper does not.
This is usually where people get angry. Why lie? If you don't know, just say you don't know.
But that reaction misidentifies the cause, so the response misses too. When the AI produced that list, it did not know it was making it up. That is not an excuse but a description of the mechanism. And changing the cause changes the prescription.
What this episode shows is that human memory fails in exactly the same way. That the failure mode is already well studied matters practically.
1932: The War of the Ghosts
Frederic Bartlett was a psychologist at Cambridge. His method was simple. He read British students a Native American folk tale called The War of the Ghosts, then had them retell it repeatedly over time: fifteen minutes later, days later, weeks later, in some cases years later.
Choosing that story was the heart of the design. To a British student the tale is full of unfamiliar names and unfamiliar logic. Its causal chain does not match Western story grammar, and supernatural elements appear without explanation. It is a story their existing frames do not hold well.
The point was to watch what happens at exactly the places that do not fit the frame.
What happened with each retelling
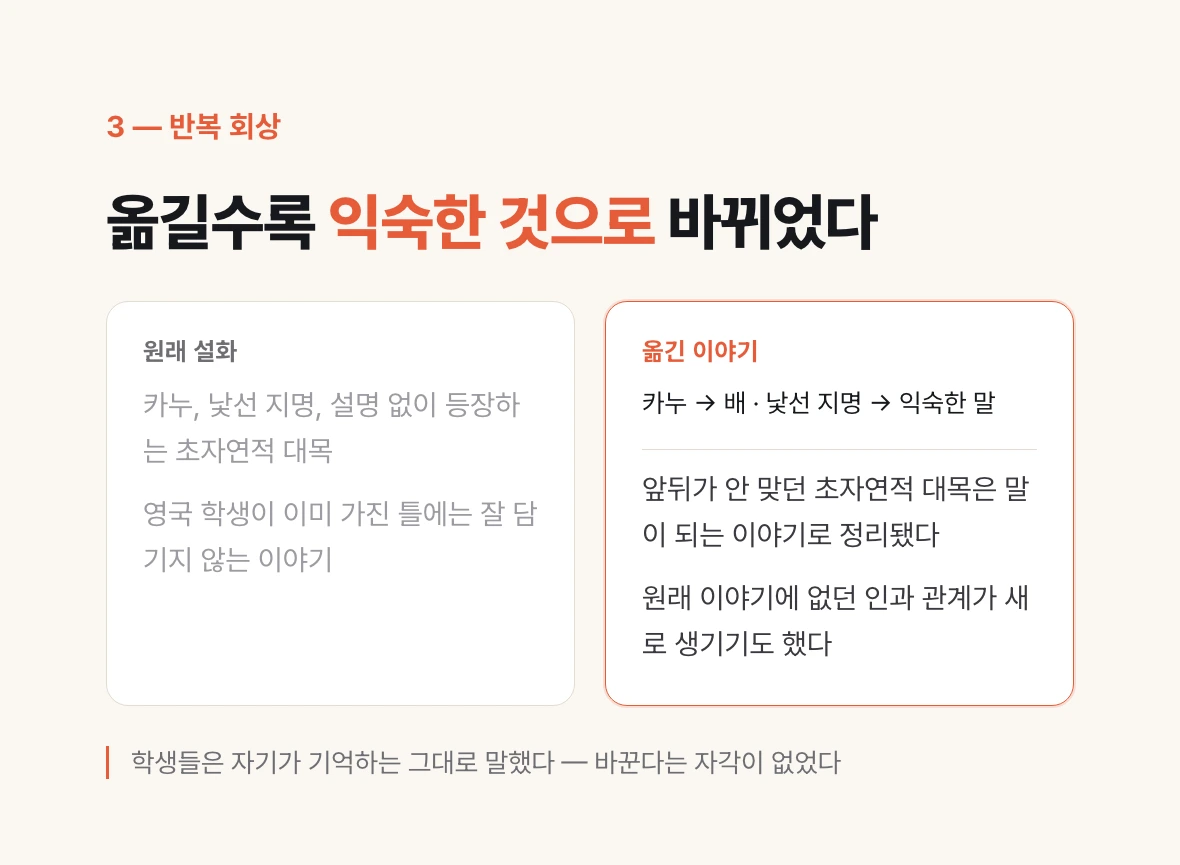
First it got shorter. Details fell away with each pass. That much is expected.
What came next matters more. Unfamiliar elements turned into familiar ones. Canoes became boats, strange place names were replaced by ordinary words, and the supernatural passages that did not hang together got tidied into a story that made sense. Causal links absent from the original sometimes appeared.
The crucial part is that the students were not lying. They reported exactly what they remembered. They had no awareness of changing anything.
Bartlett's term for this was schema. People do not hold a story like a recorder; they hold it against frames they already have. What does not fit the frame is adjusted to fit, and what is later recalled is rebuilt from that frame.
So Bartlett's conclusion is summed up this way. Memory is not retrieved, it is rebuilt.
This experiment has a sequel
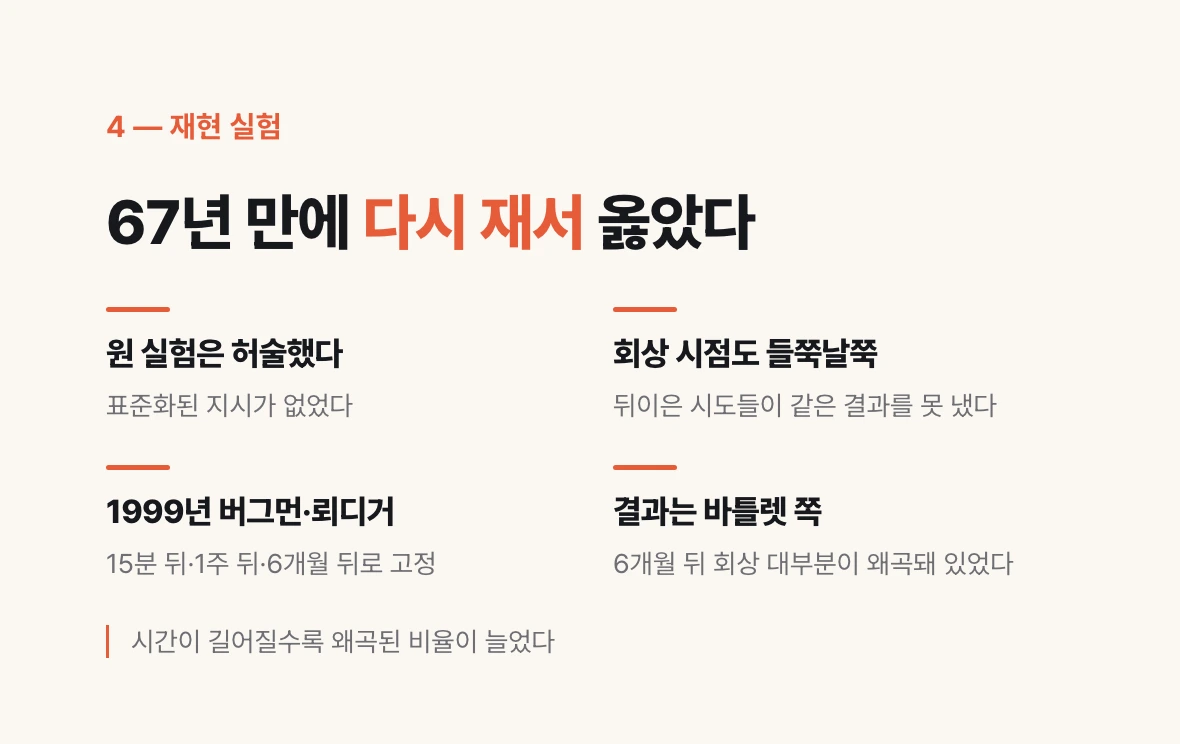
An honest addition is needed here. By present standards Bartlett's original methodology was loose. Participants got no standardized instructions, recall intervals varied from person to person, and they were not even told to be as accurate as possible.
So later attempts to walk through the procedure again failed to get the same result, and for a while it was treated as a classic that would not replicate. Citations kept coming while the ground underneath shifted.
Then in 1999 it replicated. Bergman and Roediger followed the original procedure closely but fixed recall at fifteen minutes, one week and six months. The result went Bartlett's way. Participants did not merely forget the story; they rationalized and distorted it, and the proportion of distortion grew with time. At six months most of what was recalled had been distorted.
The conclusion survived after sixty seven years. Not right because it is a classic, but right because it was measured again. This is the check this series runs every time it cites an old experiment.
Korsakoff patients: where the analogy sharpens
Bartlett's study is about healthy memory sliding gradually. The closer match for AI hallucination sits in medicine: confabulation, seen in patients with severe memory damage.
Confabulation is not lying. It is false memory arising with no intent to deceive; the patient fills the gap with whatever material comes to hand at that moment. Ask what they did yesterday and you get a detailed, coherent day that did not happen.
Two features are decisive. First, the patient does not feel that memory is empty. No signal arrives saying there is a gap. Second, because of that, they are fully confident in what fills it. No hesitation, no hedging.
As a result the patient does not recognize their own deficit and will instead try to reassure you that nothing is wrong. That last part is probably the most familiar scene of all to anyone who uses AI.
This is why saying the search failed explains AI hallucination less well. Failure implies noticing the failure, and not noticing is the whole substance of the phenomenon.
But the cause is different, so this is analogy
Draw the line precisely. Neither Bartlett nor confabulation is the cause of AI hallucination. This episode's badge is analogy, not lineage.
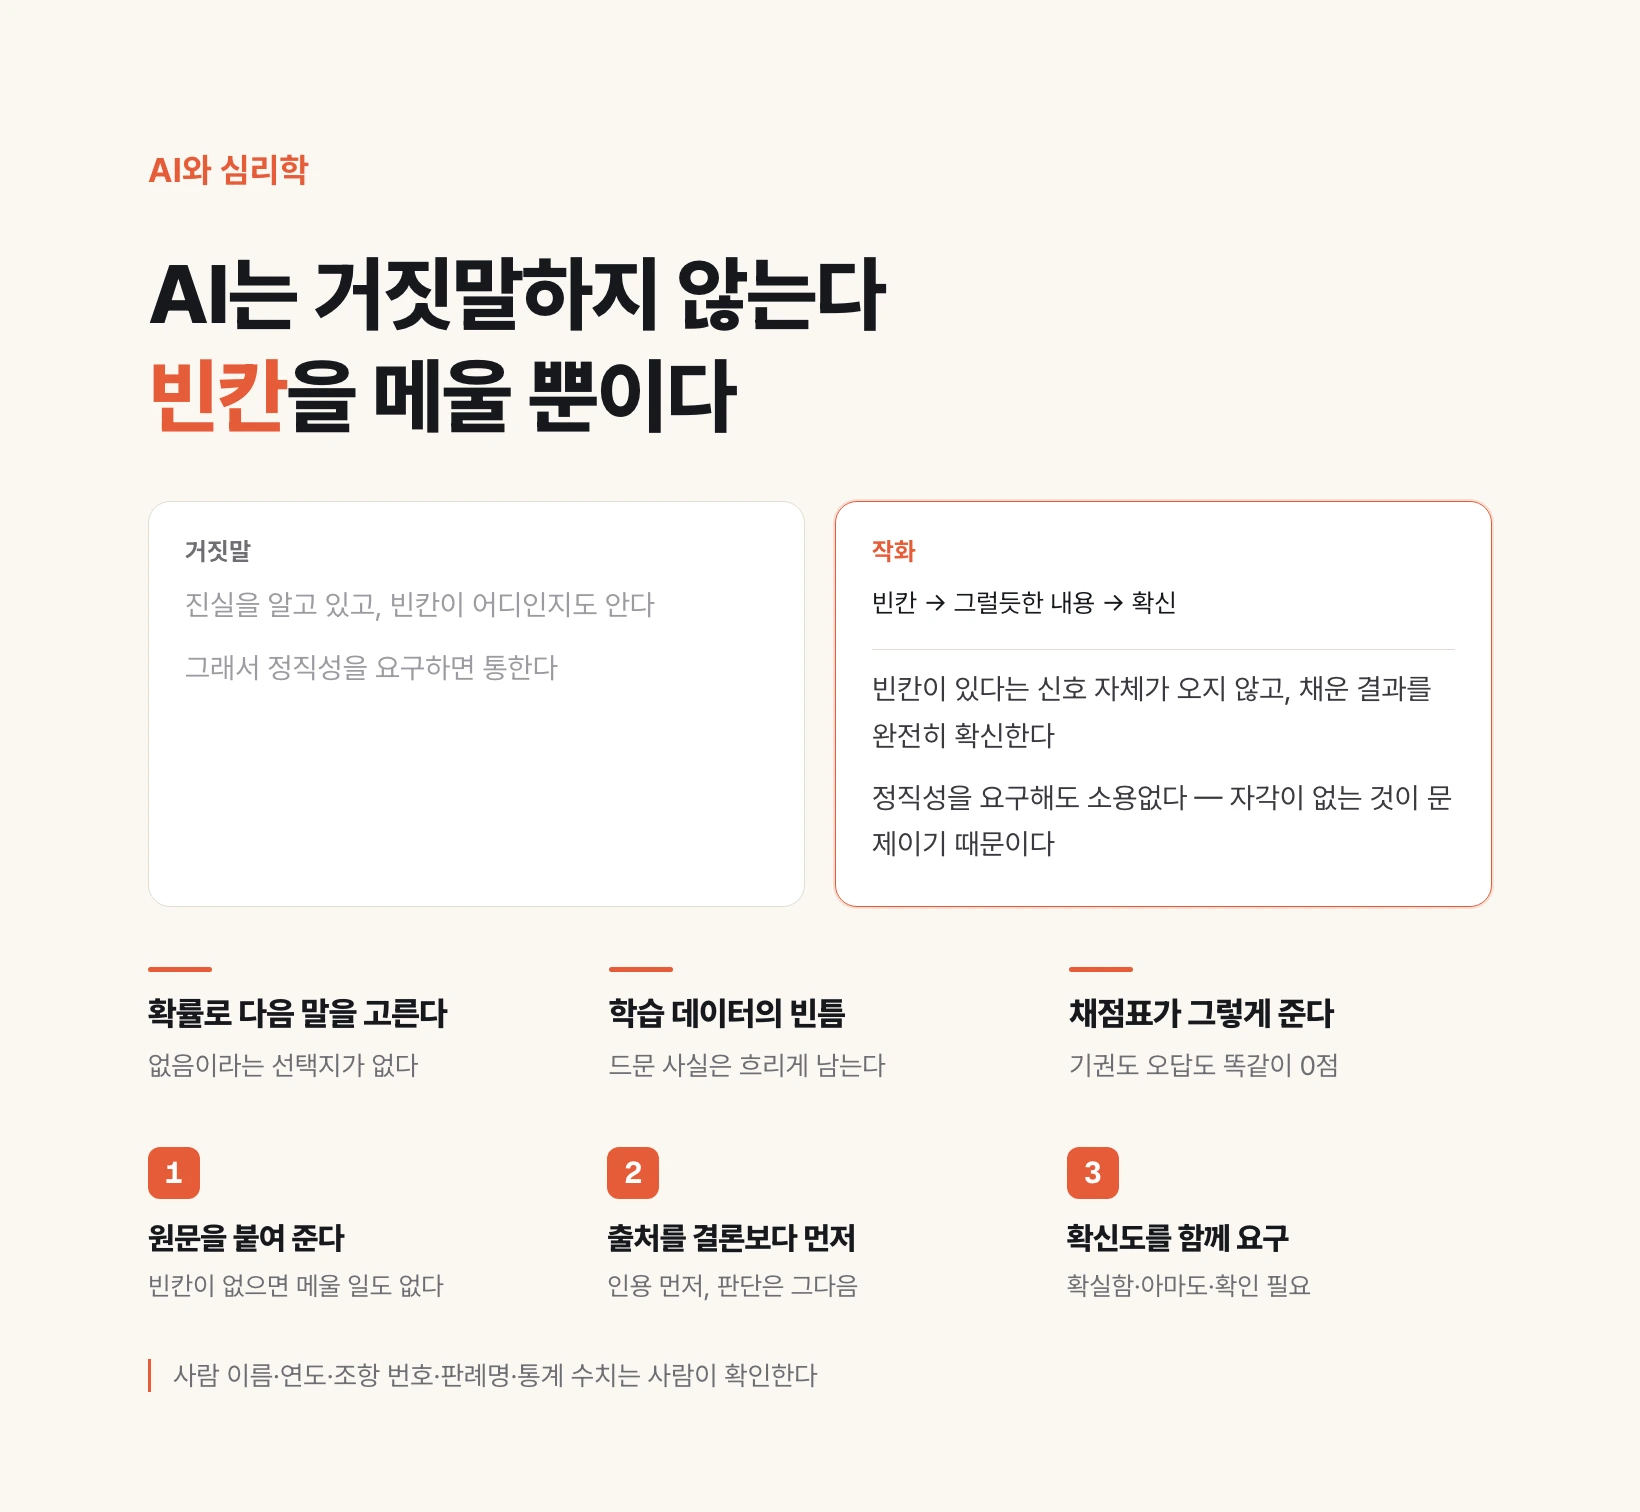
The real reasons an AI invents things come down to three. First, structure. It is built to choose the next word by probability, so something that could plausibly go in this slot always exists. Nothing is given as a default option.
Second, gaps in the data. A fact that appeared rarely in training sits faintly in the connection strengths. This is where the price of distributed representation, seen in episode three, shows up. Filling a faint spot produces a plausible shape, not one exact item.
Third, grading history. That gets its own section next.
So why bring psychology in at all? Because it is useful as guidance for response rather than as explanation of cause. See it as lying and you demand honesty. See it as a gap and you supply material. The two prescriptions differ enormously in effect.
Why not just say I don't know
The most natural objection is this. Just make it say it does not know.
A 2025 paper from OpenAI researchers took that question head on. Its argument is that hallucination persists not only because of flaws in models but because of how they are evaluated.
The exam analogy explains it fastest. On a multiple choice test, leaving a question blank scores zero. Guessing has at least some chance of being right. So a test taker maximizing score is always better off guessing. Many benchmarks used to evaluate models have exactly this shape: one point for correct, zero for wrong, zero for saying you do not know.
Under that scheme, saying you do not know is structurally a losing move. A wrong guess and an honest abstention score the same, and a guess is sometimes right. What the paper proposes is not scolding models harder but fixing the grading sheet, for instance by giving partial credit for expressing uncertainty.
The same conclusion as episode five arrives by a different route. The grading sheet makes the behavior. Flattery and confident invention are both what happens when the scoring rewards that direction.
It has already caused a courtroom incident
In 2023 a lawyer in New York filed a brief in a suit against an airline. Six of the cases cited in it did not exist. Case names and citation numbers were formatted perfectly.
The most painful part comes next. When opposing counsel said the cases could not be found, the lawyer asked the AI whether those cases were real. It said they were. In the previous episode's terms, instead of yielding to pressure it confidently backed its own answer.
The outcome was sanctions. The presiding judge imposed a monetary penalty on the lawyers and their firm, and the case became the standard reference worldwide for this kind of accident.
What to read here is not a story about blaming a lawyer. It is that perfectly formatted output invites you to skip verification. Clumsy errors stand out; errors in correct formatting pass straight through. Hallucination is dangerous not because it is wrong but because it does not look wrong.
One term only: confabulation
Confabulation is filling a gap in memory with plausible content, without awareness, and holding it as fact.
What separates it from lying is not intent but awareness. A liar knows the truth and knows where the gap is. A confabulator does not know there is a gap at all.
That distinction earns its keep because the prescriptions diverge. Demanding honesty is the right move against lying. It does nothing against confabulation, because it amounts to demanding awareness when the absence of awareness is the problem.
There is only one response to confabulation. Prevent the gap from forming.
So what changes tomorrow
Say so if you don't know is a weak prescription. It is better than nothing and does help a little, but do not lean on it. Not noticing the gap is the problem, and this asks for noticing.
Attach the source text and require answers from within it. Summaries, interpretations and comparisons should all be done with material supplied. With no gap there is nothing to fill. This is the single highest leverage move and it comes before every other technique.
Make it write the source before the conclusion. Specify the order: quote the supporting sentence verbatim from the material, then judge. With nothing to quote, it stalls right there, which shrinks the room to invent. Reverse the order and it will set the conclusion first and manufacture matching support.
Ask for a confidence level alongside. Requiring each item to be marked certain, probably, or needs checking is not perfect, but it is usable for deciding what to verify first.
List the expensive to verify items in advance. Personal names, years, clause numbers, case names, statistics. These five are where plausible errors live, and they are also where correct formatting hides them. Leave that column as the human's job.
In short: do not demand honesty, supply material. And the more perfect the formatting, the more you should doubt it.