Training Is Finished, but the Model Is Unusable
In the previous piece, training was completed by adjusting parameters little by little. What came out of it is a single model with optimized weights.
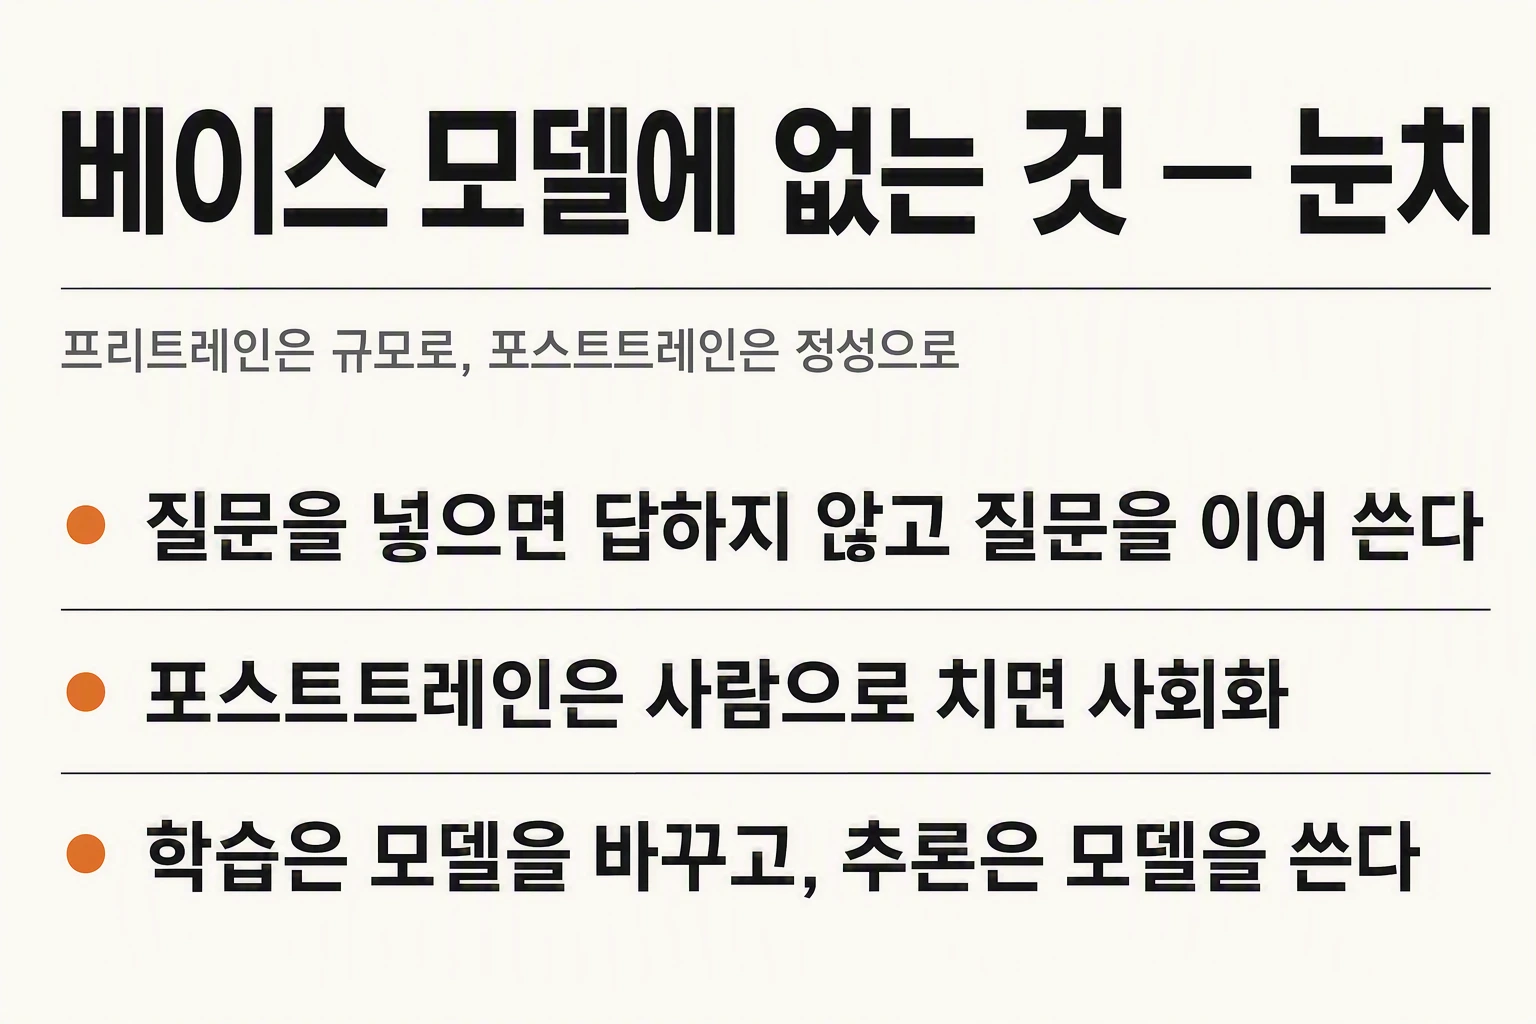
Yet when you put a question to this model, it does not answer. It continues the question instead. Feed it 'What is the capital of Korea?' and it keeps producing similar sentences: 'And what is the capital of Japan? The capital of China is...'
Nothing is broken. It is doing exactly what it learned. This model was trained on one thing only: looking at what came before, what is natural as the next token. It never learned that an answer follows a question.
A model in this state is called a base model, and the process up to this point is called pretraining. The 'pre' means this is still an earlier stage.
What a Base Model Lacks — Situational Sense
If what a base model lacks had to be named in one word, it is situational sense. It has no feel for behaving in a way that fits the situation.
Suppose you want to use it as a coding tool. Then predicting the next fragment of code well is not enough. Given an error log it has to point out what the problem is, return the corrected code in the expected format, and explain where an explanation belongs.
Having it write a report calls for yet another form. The summary comes first, the supporting evidence follows, and the length has to match the request.
All of these are demands on a different level from 'the natural next token.' Additional training is therefore required, and that stage is called post-training. In human terms it is closer to socialization.
Fine-tuning — the Console Is Not Rebuilt
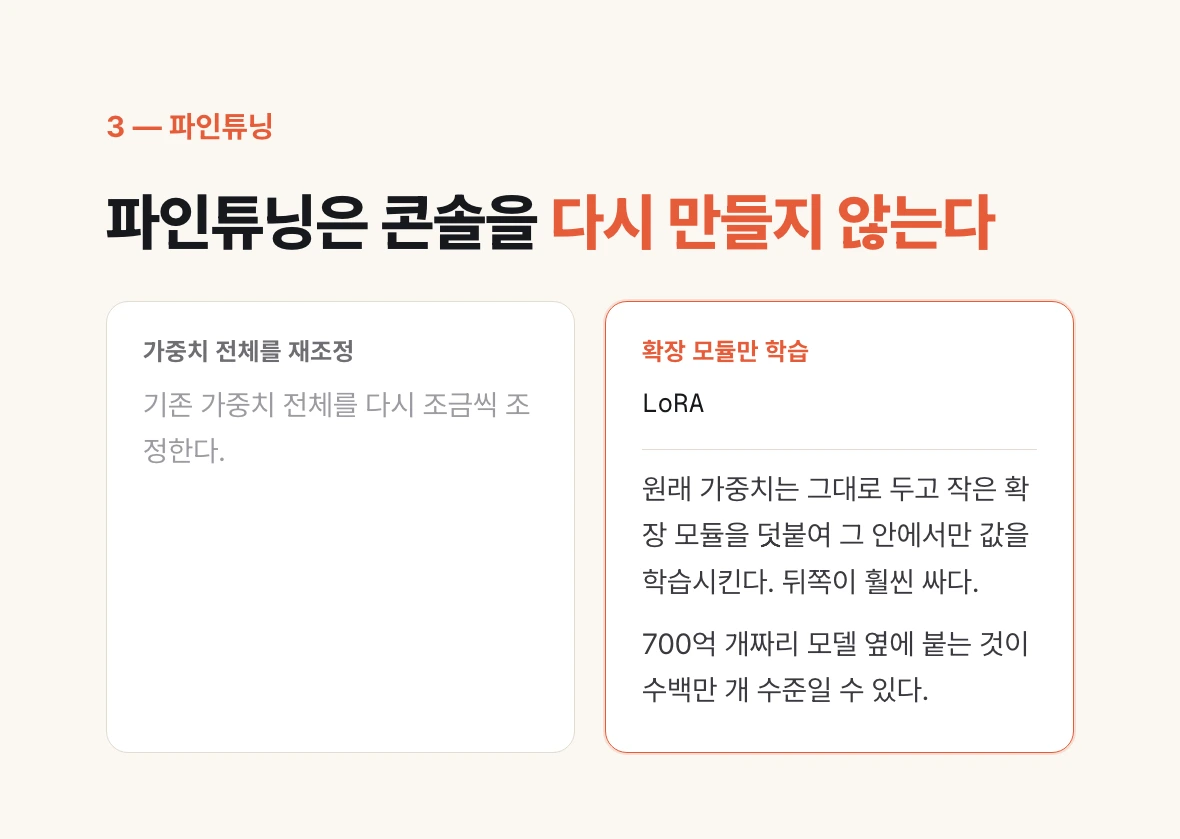
The representative method of post-training is fine-tuning. The important point here is that pretraining is not done over again from scratch.
Continue the DJ console analogy from the previous piece. There is already a console that has been tuned well. Fine-tuning is not discarding that console and building a new one; it is working on the console you already have a little further.
The ways of working on it split broadly into two. One is to adjust all of the existing weights again, little by little. The other is to leave the original weights as they are, attach a small extension module, and learn values only inside it. The latter is far cheaper and goes by names such as LoRA.
The module being attached is very small compared with the original model. What sits beside a model of seventy billion may be on the order of a few million. Drawn to scale, the ratio would not even show up at the thickness of a hair. Even so, the behavior of the model changes noticeably.
The Ingredients Differ in Scale Too
The data used for fine-tuning is different in character from pretraining data. Rather than scraping together text from the internet, question-and-answer sets are built in the form of 'asked this way, answered this way.'
This takes a great deal of human work, because people have to decide what a good answer is. The volume therefore lands somewhere between a few hundred thousand and a few million items.
That sounds like a large number, but it is very small next to the amount of text that went into pretraining. This is the point. The earlier stage pushes through with scale, and the later stage refines with care.
Fine-tuning is not the only option either. Reinforcement learning style methods, which set the direction by comparing good answers against bad ones, are used alongside it. Those methods design what counts as having done well, instead of preparing question-and-answer sets.
loss — Training Is a Game of Reducing How Wrong You Are
Here it is worth noting one concept that runs through training as a whole. The number that expresses how wrong the model was on one round of learning is called loss.
Training is ultimately a game of minimizing this loss. Put the number of iterations on the horizontal axis and loss on the vertical axis, and the curve drops steeply at first, then flattens out, and from some point on it no longer goes down.
That is usually where training stops. The signal to end is not 'this is too wrong, start over' but 'doing more will not bring it down any further.'
And loss never becomes zero. A state of getting 100 percent of answers right never arrives; the model only approaches it. This is where the statement that there is no 100 percent in AI results comes from.
A Common Tangle — Token Count and Parameter Count Are Unrelated
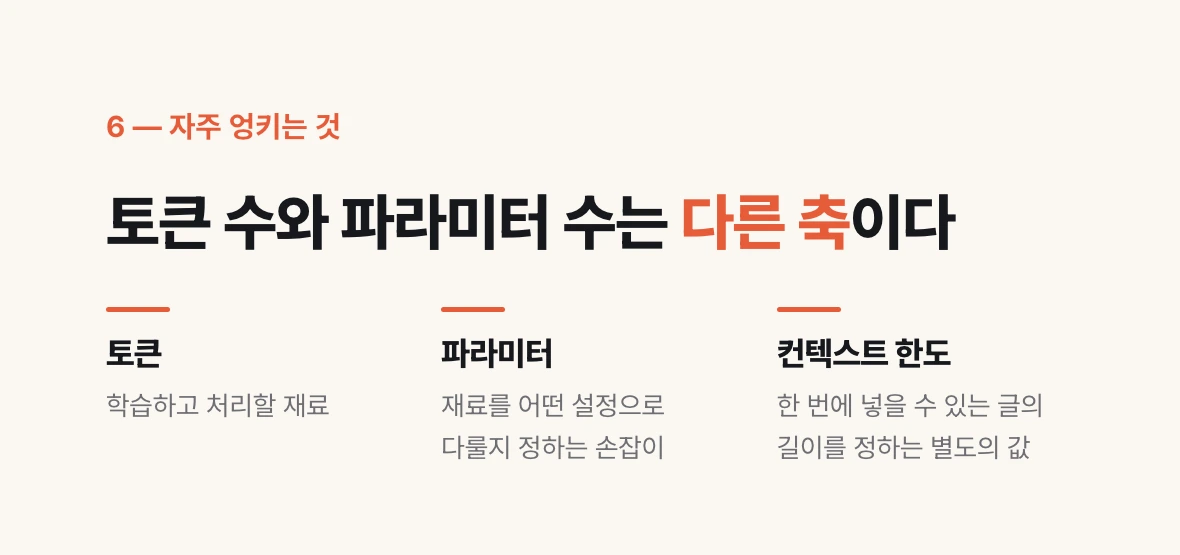
A question that comes up often is whether more parameters mean more tokens can be handled. The two are separate axes.
In washing machine terms, tokens are the laundry and parameters are the wash cycles. How much clothing goes in today and how many cycle settings there are amount to separate stories.
Tokens are the material to be learned and processed, and parameters are the knobs that decide with what settings that material is handled. Having more parameters does not make the text you can put in at once any longer. That length is set by a separate value called the context limit.
The word labeling also gets mixed in frequently. Labeling mostly refers to building datasets where people attach the correct answer one by one, as in image recognition. Pretraining does not need that work, because the text itself already holds the answer.
Why There Are So Many Models
Pretraining is not something anyone can do. It means running large-scale compute resources for months at a time, so the places that can actually do it are not many.
Yet the world has a great many models. These two facts look inconsistent with each other, and the answer lies in post-training.
This stage is the domain of recipes. The outcome changes with which question-and-answer sets are used, what is counted as having done well, and in what order the training runs. Even starting from the same base model, a difference here produces a model with a different character.
This is also why benchmark scores vary from model to model. Whether a model leads at coding or at document summarization usually comes down to a difference in this recipe rather than the scale of pretraining.
That is the reason parameter count alone is a poor basis for choosing a model in practice. What to look at is the benchmark for tasks similar to the work you intend to do.
This Is Where Training Ends
A corpus was gathered and turned into tokens, parameters were refined through next-token prediction, and post-training taught situational sense. A model that can be served now exists, and attached to a chat screen it becomes the tool we use.
Everything seen so far, though, is training. It has been the story of building a model.
From the next piece an entirely different story begins: the process by which a finished model takes our question and produces an answer, which is inference. Mixing the two makes the conversation go astray, so it is better to keep them clearly separated. Training is the work of changing a model, and inference is the work of using a model that has never changed.