Why one spreadsheet does not work
Say you run a comic book rental shop. You need a member roster, a list of the comics you hold, and a record of who borrowed what and when they returned it.
Could all of that go on one spreadsheet? You could force it, but it stops being usable fast. Members on the left, books in the middle, loan records starting from some row further down is not something anyone can maintain.
So you split into sheets. Members on the member sheet, books on the book sheet, loan records on another. Then you link them. The fact that this member borrowed this book gets written as a link between two sheets.
A relational database is exactly that shape. The relational in the name refers to those links.
Tables, rows, columns, and keys
One table is a table. It corresponds to one sheet in a spreadsheet.
The top row holds column names: id, name, phone. Below it, records stack one per row. One member is one row; one book is one row.
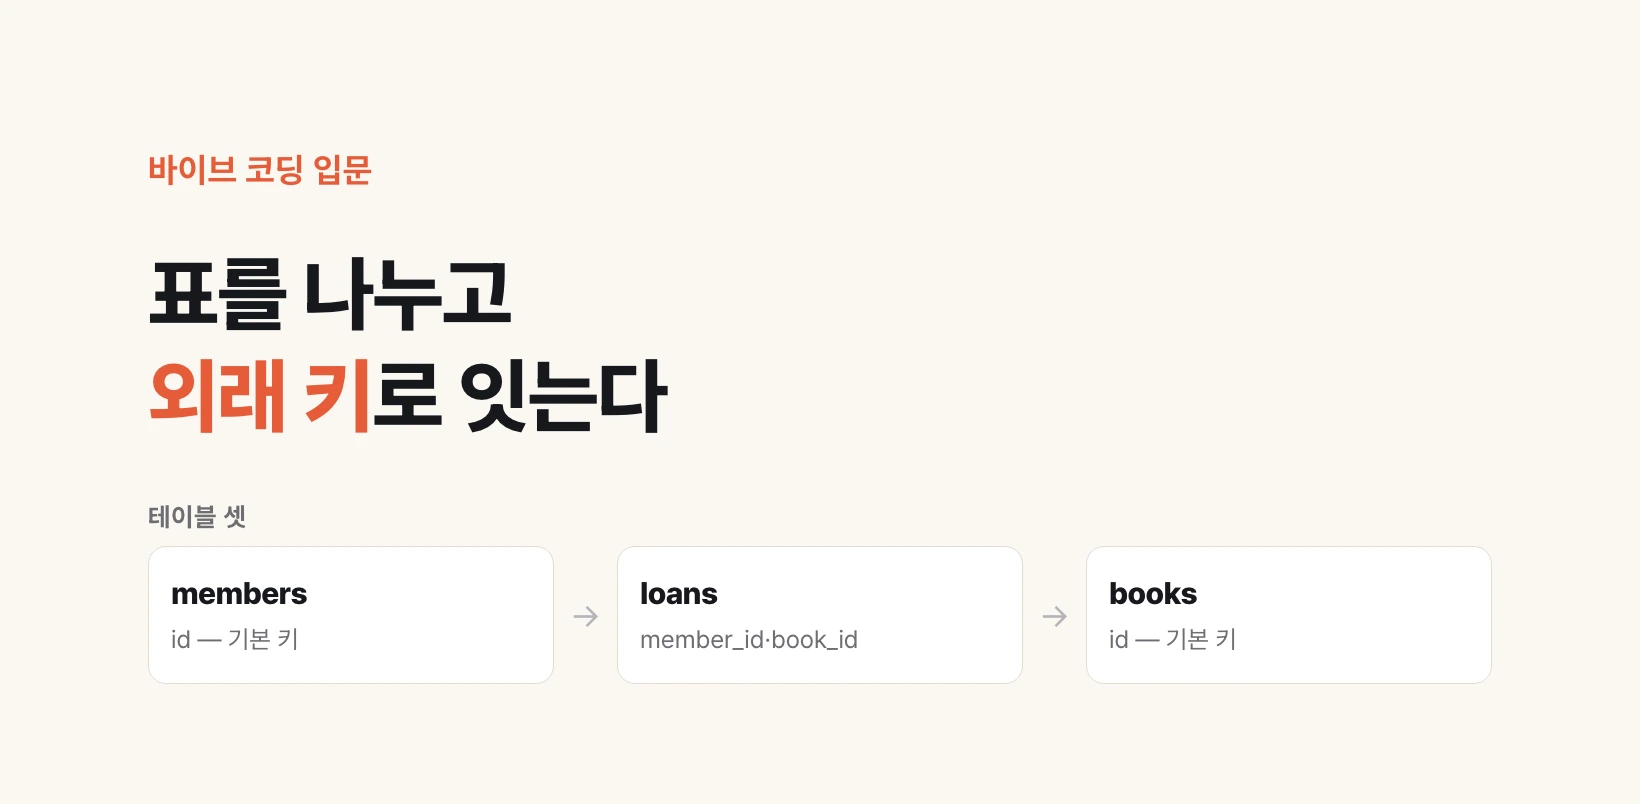
Now the linking. Say a member in the member table has id 1. Put a member id column on the loan record table and write 1 in it, and you have expressed that this loan belongs to that member. A value pointing at another table like that is a foreign key.
You also need a value that uniquely identifies each row, like the id in the member table, one that never repeats. That is the primary key. A foreign key, in the end, points at another table's primary key.
members            books              loans
─────────────      ─────────────      ──────────────────────
id  name           id  title          id  member_id  book_id
1   Minsu          7   Slam Dunk 1    1   1          7
2   Seoyeon        8   Slam Dunk 2    2   1          8
                                       3   2          7

loans.member_id is a foreign key pointing at members.id
loans.book_id   is a foreign key pointing at books.id
A schema is rigid, and stable for the same reason
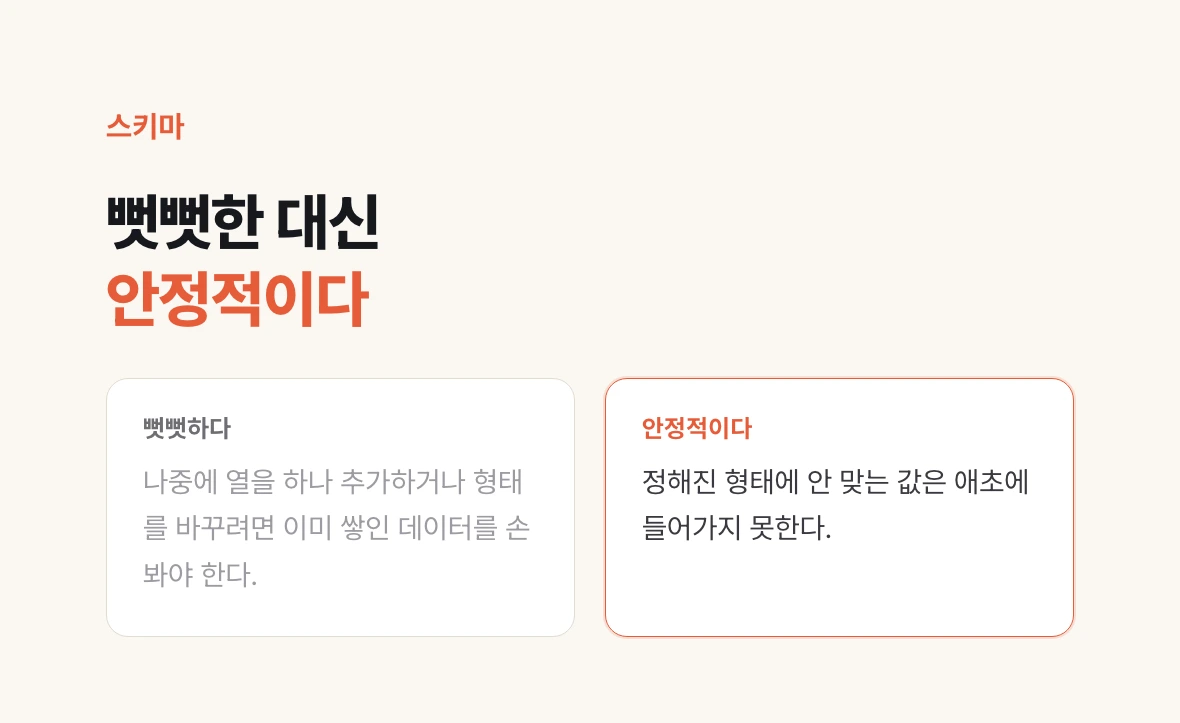
The shape of a table is its schema: which columns exist, and what kind of value each column can hold, settled in advance.
What gets settled is fairly fine-grained. This column takes numbers only, that one text up to a length, this value cannot be empty, that one cannot repeat across rows.
It is rigid. Adding a column later or changing a type means dealing with data already stored. In exchange it is stable: a value that does not fit the declared shape never gets in.
Which makes deciding how to split tables and how to join them a specialty in itself. As a service grows, someone is assigned to that design alone. The same data, split differently, becomes either manageable or unmanageable later.
Queries, and the databases that are not relational
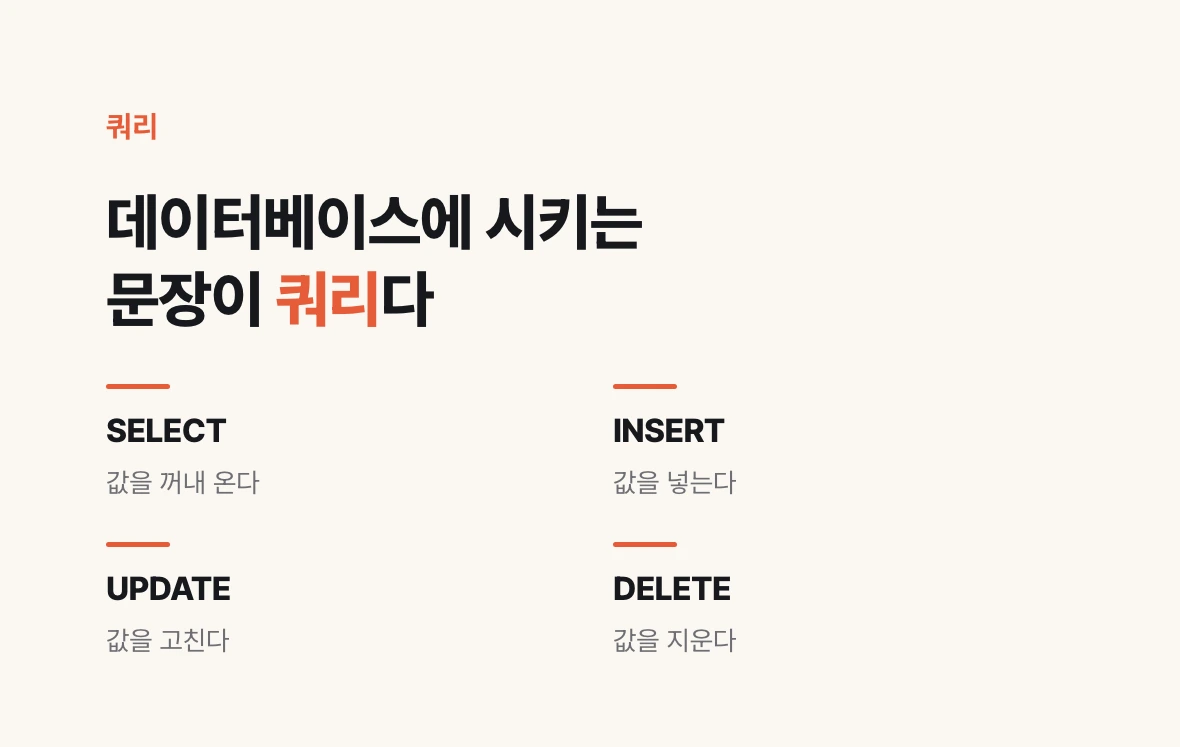
A statement telling a database to do something is a query. Pulling values out, putting them in, changing them and deleting them all happen through these statements.
Every product with SQL in its name speaks them. PostgreSQL is one of those and turns up constantly in vibe coding projects. The statements look broadly alike, so learning one carries over to the others.
Writing queries directly in code has become less common. Tools that compose them for you are well established, so defining the shape of the data in the backend code from the previous post is often enough; the tool writes the query.
There are non-relational kinds too. Document databases store each item as a whole document and suit data whose shape changes often. Graph databases store only what is connected to what. Still, the default for a web service remains relational. Next we look at what does not go in these tables: where images and video live.
SELECT title FROM books WHERE id = 7;

INSERT INTO loans (member_id, book_id) VALUES (1, 7);

UPDATE members SET name = 'Minsu' WHERE id = 1;

DELETE FROM loans WHERE id = 3;