Those few seconds holding a phone number
While you hunt for paper to write down a phone number someone is reading out, you repeat it to yourself. Once written, it is gone within seconds.
Where was the number during those seconds? Not in long term memory, since it vanished. But it was not nowhere either. While you rehearsed it you clearly had hold of it. And the moment you stop rehearsing, it goes.
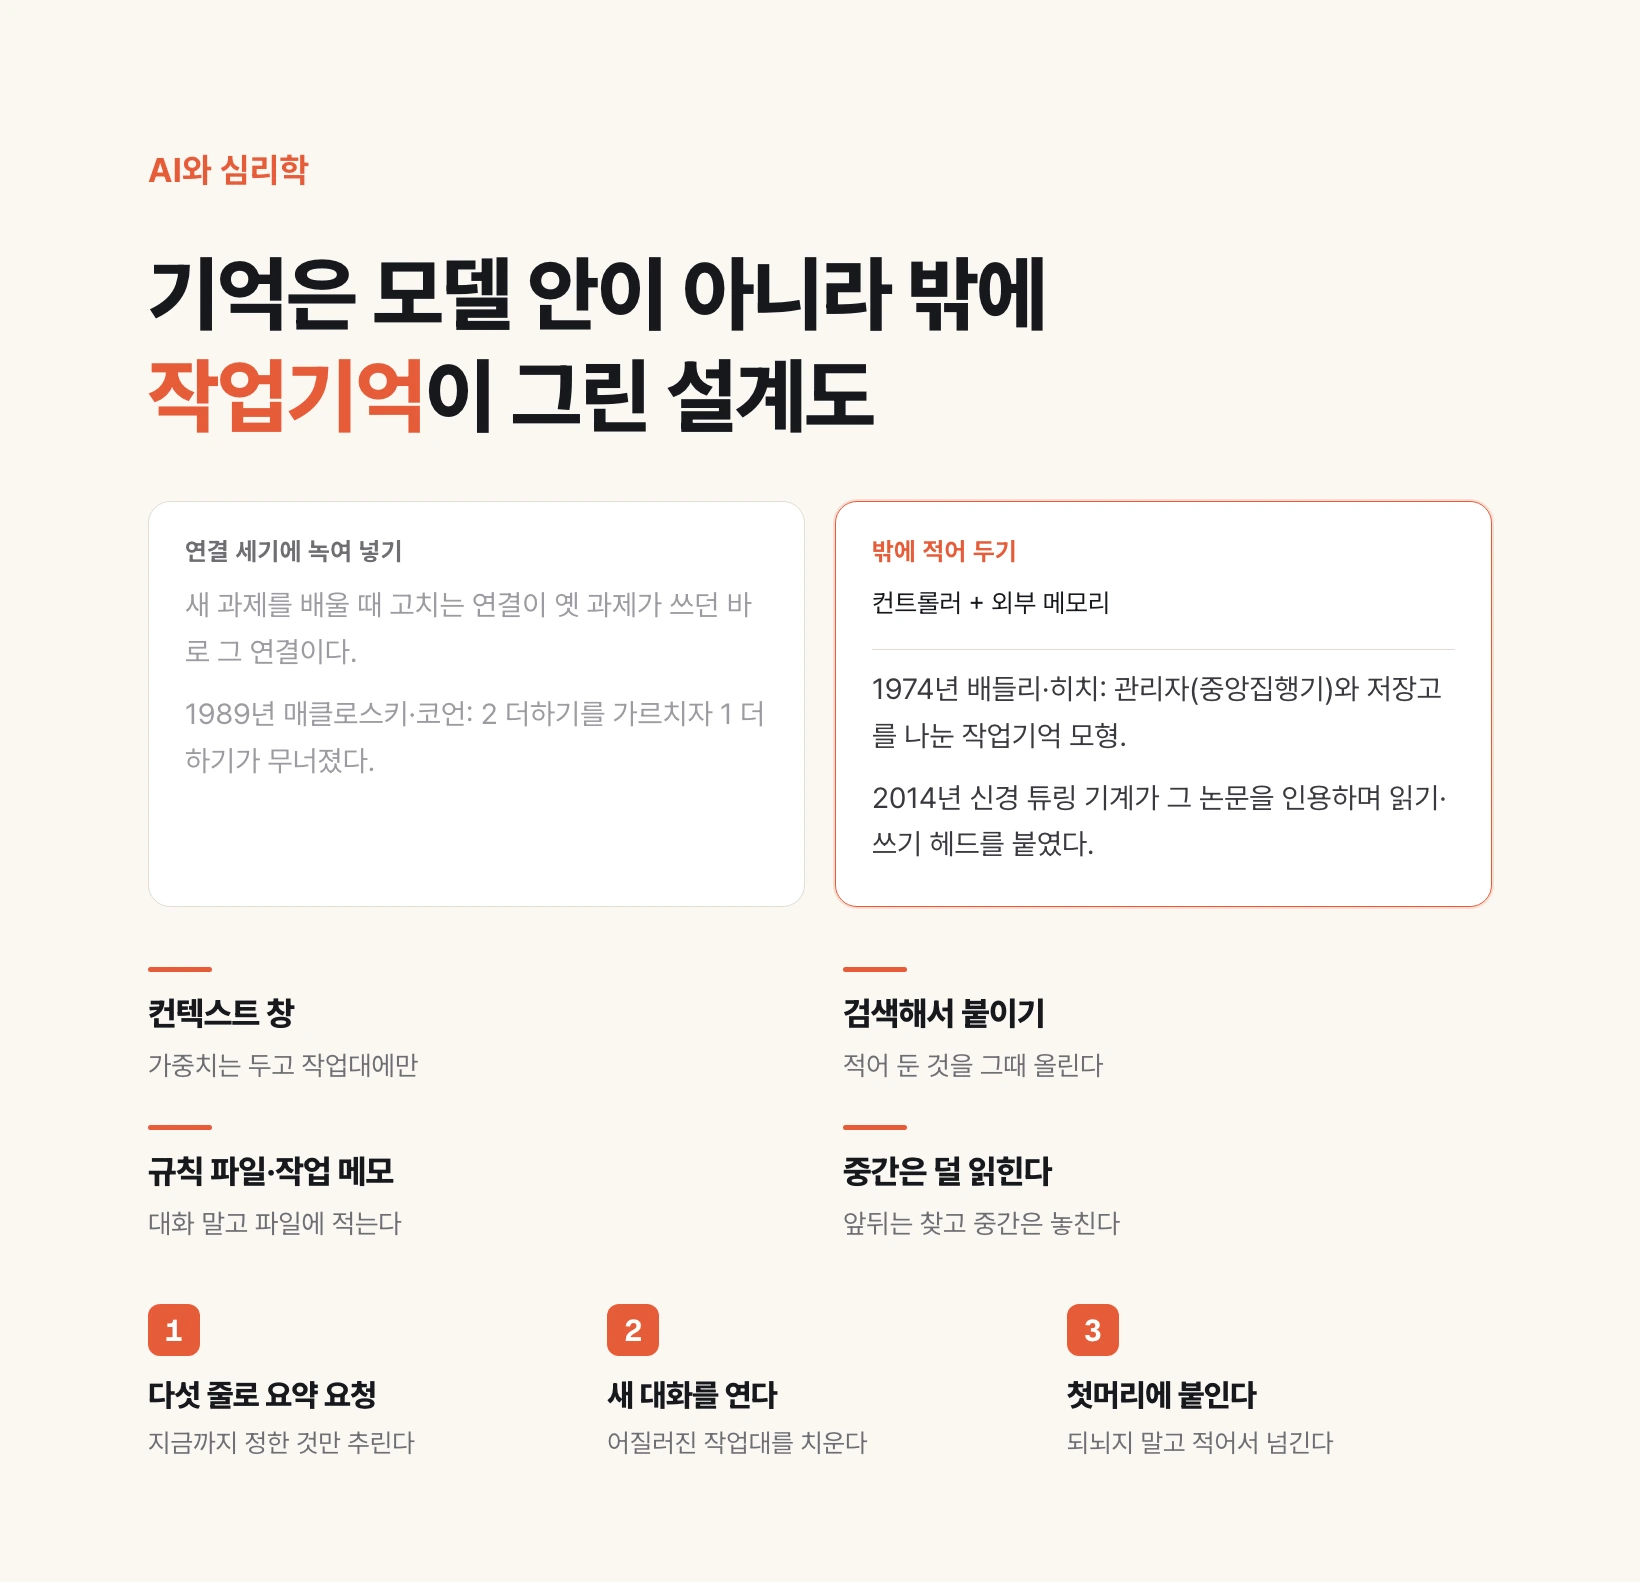
Psychology's name for that place is working memory. The concept later crossed over into AI architecture intact. This episode follows that route.
1974: memory broken into parts
Until then short term memory was treated as a single store. One room where information sits briefly, with a fixed amount it can hold.
In 1974 Alan Baddeley and Graham Hitch offered a different picture. Short term memory is not one room but a combination of parts with different jobs.
The phonological loop is where speech sounds are rehearsed internally. That is where the phone number is held. The visuospatial sketchpad briefly holds shapes and positions; you use it when picturing a furniture layout or recalling which way to turn in an unfamiliar building. The central executive is the manager that directs those two, deciding what to attend to, what to bring up, and what to drop.
You do not need to memorize the part names. Remember one thing: manager and store are separate. The part that thinks and the part that writes things down are distinct. That picture is this episode's blueprint.
The evidence those parts are real
Anyone can carve a model into pieces. Baddeley's version earned its standing by showing effects that only that split explains.
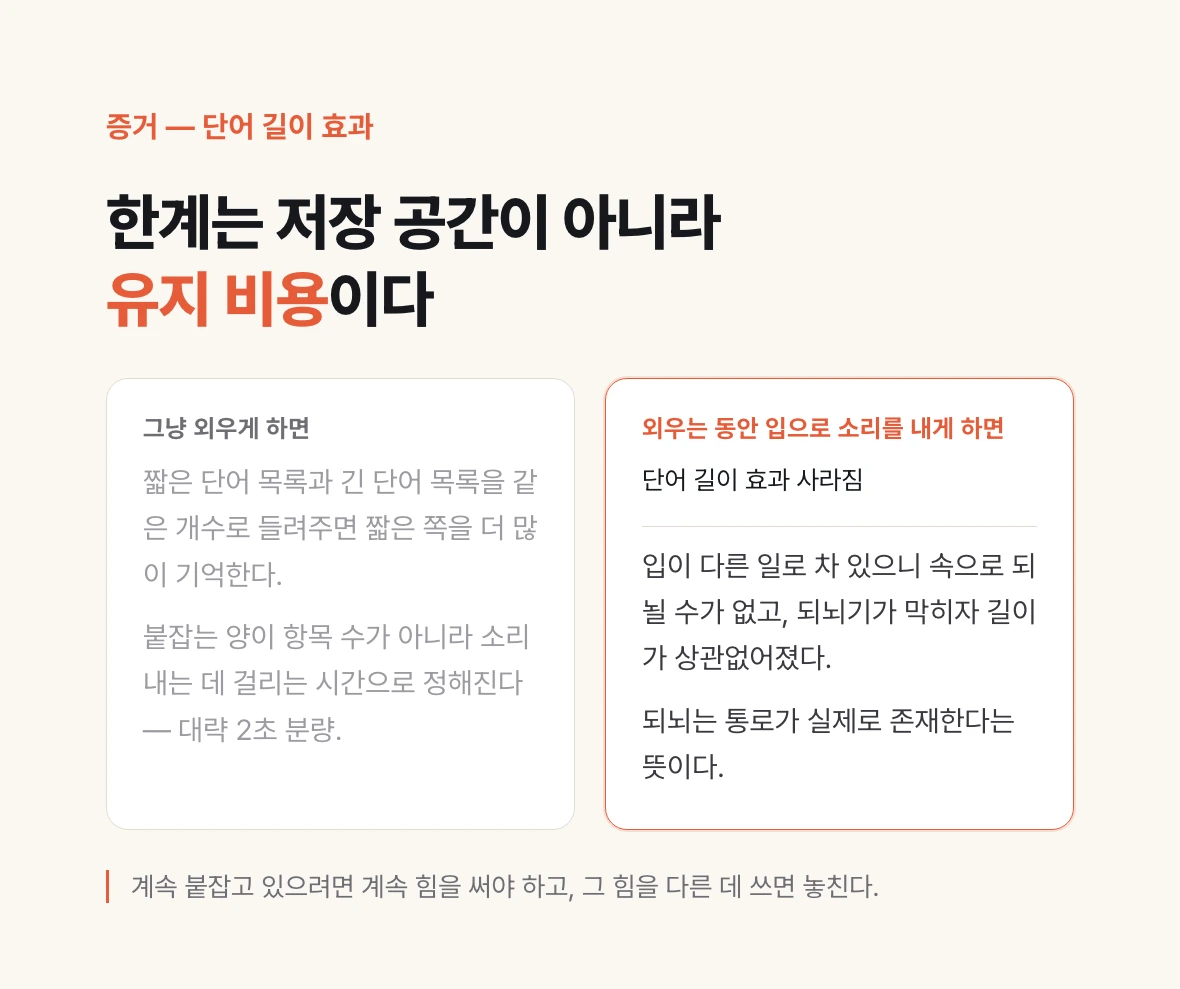
The most famous is the word length effect. Give people a list of short words and a list of long words, the same number of items each, and they recall more of the short ones. Same count, different result, because what the phonological loop holds is set not by number of items but by how long they take to say. The limit came out at roughly what you can pronounce in about two seconds.
A more decisive experiment goes further. If people keep uttering a meaningless sound aloud while trying to remember, the word length effect disappears. The mouth is busy, so internal rehearsal is blocked, and once rehearsal is blocked, length stops mattering. That means the rehearsal channel really exists.
The conclusion holds up this entire episode. The limit of working memory is not storage size but maintenance cost. Holding on takes continuous effort, and spending that effort elsewhere means dropping it.
The workbench is far smaller than you think
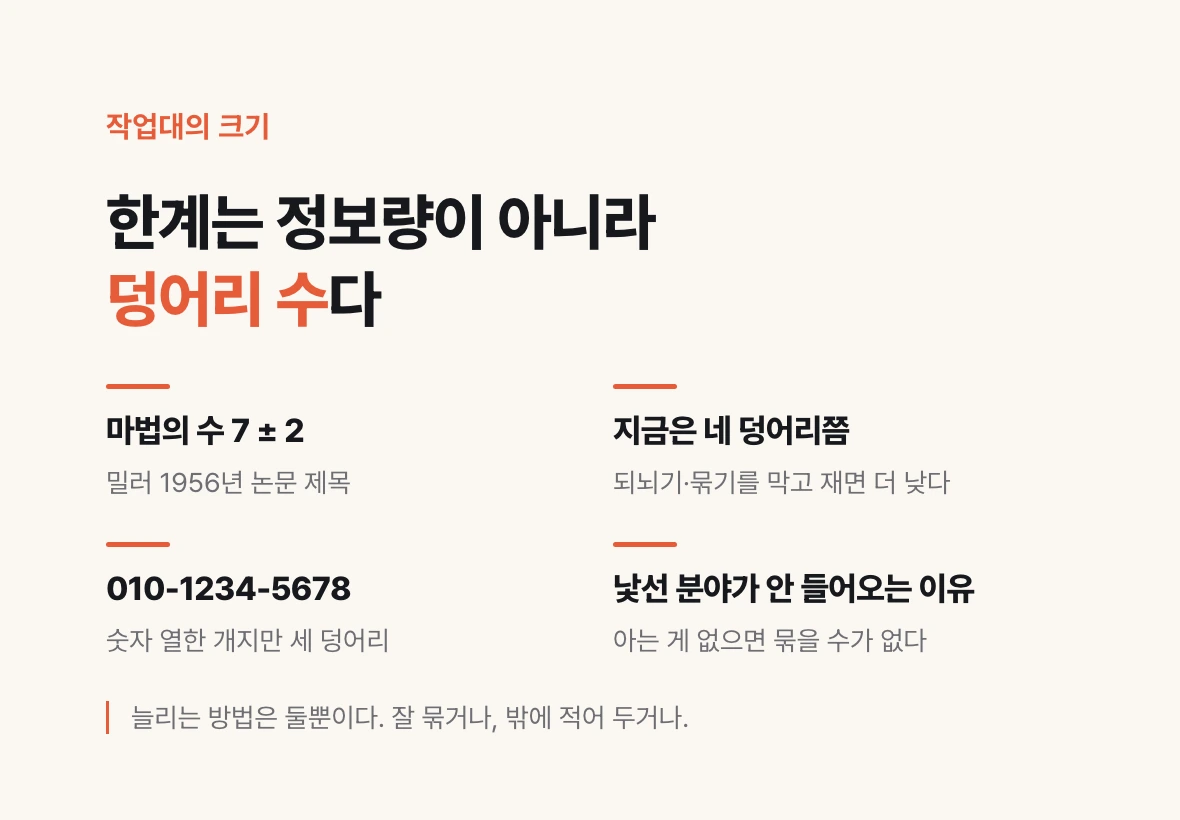
There is a famous number for how small that bench is: the magical number seven, plus or minus two, from George Miller's 1956 paper. It spread as the claim that people hold about seven items at once.
That number is not used as is anymore. Later work argued that once you block rehearsal and grouping and measure cleanly, the limit is far lower, and an estimate of around four chunks is widely cited. Miller himself called the number magical half in jest.
What matters is not the figure but the unit. The limit is in chunks, not in amount of information. A phone number has eleven digits but we hold it as three groups. Bundling items into one slot like that is called chunking. It is why an unfamiliar field is unusually hard to take in: with no prior knowledge you cannot bundle, so every item eats a slot of its own.
So there are only two realistic ways to extend working memory. Chunk better, or write it outside. People have done the second with paper and whiteboards for a long time. Neural networks ended up on the same road.
The network's problem: new learning erases old
As the previous episode showed, a neural network dissolves what it learns into connection strengths. Nothing is stored as an entry anywhere; it is scattered across the whole. That method has a nasty side effect.
In 1989 Michael McCloskey and Neal Cohen demonstrated it cleanly. They trained a network on single digit addition facts involving adding one until it did them well, then trained it on facts involving adding two. It now did the twos well, and its performance on the ones collapsed. Nobody told it to erase them.
The reason is structural. The connections adjusted while learning the new task are the very connections the old task was using. If each item had its own slot there would be nothing to overwrite, but scattered across the whole, they overlap. The phenomenon is called catastrophic forgetting.
In human terms it would be like erasing an old friend's name every time you learn a new person's. Making the model bigger does not fix it. It is not a capacity problem but a property of how storage works.
2014: attaching a notepad to a neural network
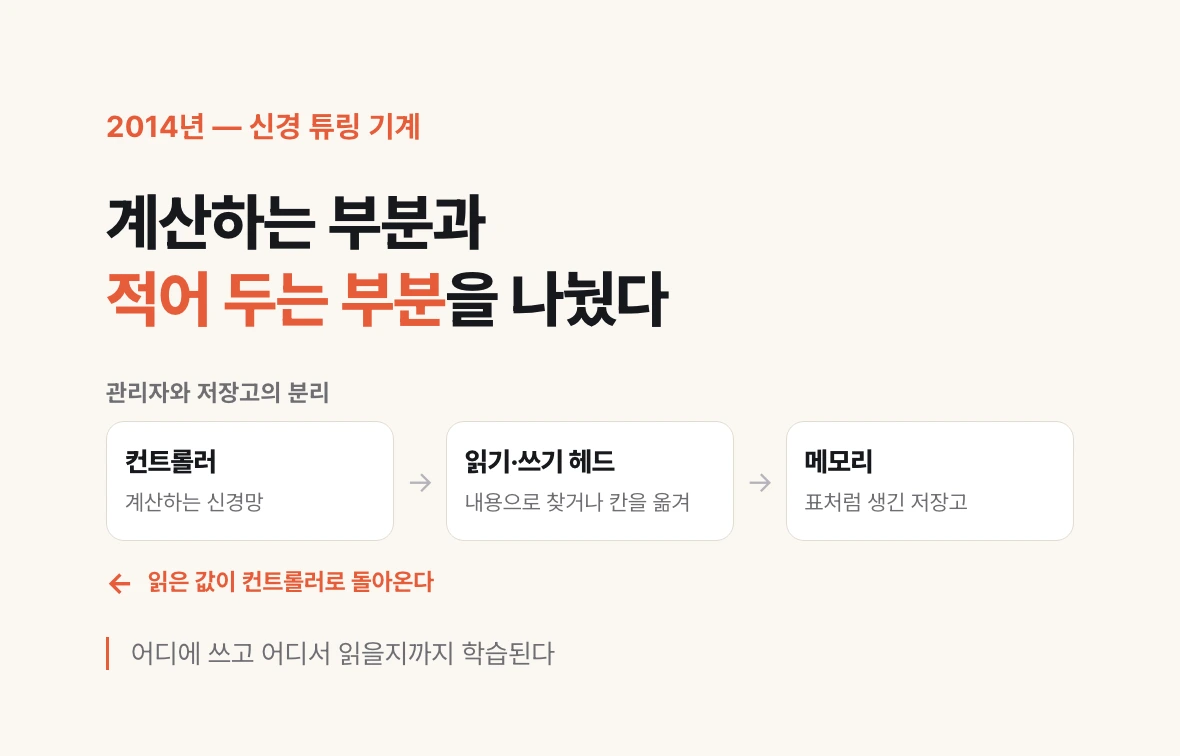
The solution Alex Graves and colleagues published in 2014 as the Neural Turing Machine is Baddeley's picture exactly. It separated the network that computes from the memory that holds values.
The structure works like this. A network called the controller plays the manager. Beside it sits a separate memory shaped like a table, and the controller writes to or reads from particular rows through read and write heads. Which row to use is decided two ways: by content, or by shifting some number of rows from where it was looking.
The core of the design is that where to write and where to read is itself learned. No human sets the rule; in the course of getting answers right, how to use the notepad is learned along with everything else. As a result the machine copied sequences longer than any it saw in training. That means it acquired the procedure rather than memorizing examples.
The evidence that the paper drew on cognitive science as more than metaphor is in its references. It cites Baddeley and Hitch's 1974 working memory and the central executive directly. It did not, however, transcribe the diagram into circuitry. It took the idea of splitting manager from store and redesigned it as a neural network.
Where that lineage sits today
The Neural Turing Machine itself is not in use now. But its idea is right there in the tools we use every day.
The context window attached to a chat is the nearest instance. The model's weights stay fixed and only what is needed goes onto the bench for that moment. Storing conversations as documents and pulling in the relevant passage is the same idea. We call it retrieval, but what it does is put something written outside onto the bench when needed.
An agent keeping working notes in a file, project rules living in a separate file that gets read every time, a conversation history summarized and pasted at the head of the next one, are all the same family.
They share one thing. Memory is not pushed inside the model but written outside it. Baddeley's split of manager from store still stands, forty years on.
One term only: working memory
Working memory is the capacity to hold and operate on the information a current task needs.
It is often confused with short term memory, but the emphasis differs. Short term memory asks how long you hold something. Working memory asks what you do with it while holding it. A bench, not a warehouse.
So saying someone has good working memory is closer to saying they manage it well than that they hold a lot. What to put on the bench and what to clear off, when to write something out and when to bring it back, is what actually separates performance.
The same is true of using AI. A wide context window and using that window well are different questions.
What actually happens in a long conversation
Most people have had the experience of answers getting worse as a conversation runs long. A model that understood you at first starts ignoring things you settled earlier.
There is measured ground for this. In studies that give a long input and plant the supporting passage near the start, in the middle, or near the end, accuracy is highest when it sits at the start or the end and drops noticeably in the middle. Being inside the window does not mean being used equally.
One more effect stacks on top. The longer a conversation runs, the more the early instructions get buried under everything said since. They are buried well before they fall out of the window. Structurally it is the same as people forgetting the opening agreement three hours into a meeting.
So reading a sudden drop in quality as the model getting dumber leads to the wrong response. The bench is cluttered, and the fix is not more explanation but cleaning up.
So what changes tomorrow
Put what matters in a file, not in the conversation. Project rules, terminology, prohibitions and tone should go into a file or a memory feature rather than being said once near the top of a chat. In the previous episode's phrasing: do not leave it to connection strengths, write it on the notepad.
When a conversation starts wandering, open a new one. But do not just open it; carry something over. Ask for a five line summary of what has been decided, then paste those five lines at the head of the new conversation. This is where human rehearsal belongs. Rather than spending effort holding on, write it down and hand it over.
When pasting long material, repeat the instruction after it as well. If the material goes in and the question sits only above it, that question gets buried in the middle. Wrapping the same instruction before and after avoids much of the position problem.
Give one conversation one job. Asking for an email draft in the window where you were fixing code mixes two kinds of thing on the bench, and the next code answer gets worse. It is the same place humans lose out on multitasking.
In short: a workbench is not widened, it is cleared. And before you clear it, write things down.